
はじめに
『Pythonで学ぶ空間データサイエンス入門』の独学時のまとめノートです。「定義編・導出編」「作図編・実装編」「可視化編」の三部構成でモデルやアルゴリズムの理解を目指します。
本の内容から寄り道・回り道しながら進めます。本を読んだ上で補助的に読んでください。
この記事では、Pythonを使って、LISAクラスターマップを作成します。
【前の内容】
【他の内容】
【今回の内容】
2.4 LISAクラスターマップの作成
ローカル・モランのI(LMI・local Moran's I)や空間ラグ(SL・spatial lag)を可視化する図であるLISAクラスターマップ(LISA cluster map・local indicators of spatial association cluster map)を作成します。
空間ラグについては「2.3:空間ラグの定義式【空間DS入門のノート】 - からっぽのしょこ」、LMIについては「2.4:ローカル・モランのIの定義式【空間DS入門のノート】 - からっぽのしょこ」、LMIの優位性検定やp値については「
【Python】2.3:グローバル・モランのIの優位性検定の実装【空間DS入門のノート】 - からっぽのしょこ」を参照してください。
利用するライブラリを読み込みます。
# ライブラリを読込
import geopandas as gpd
from pysal.lib import weights
import numpy as np
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColormap # 配色用
import matplotlib.patches as mpatches # 凡例用
from pandas.api.types import CategoricalDtype # 配色用
import japanize_matplotlib # 日本語の描画用
データの読込
まずは、地理空間データを読み込んで、前処理を行います。
詳しくは本の1.1節を参照してください。
国土数値情報ダウンロードサイトのデータの場合
この例では、国土数値情報ダウンロードサイトから2026年版(基準年)の大阪府の行政区域データ・地価公示データをダウンロードして、大阪市のデータを利用します。
「国土数値情報ダウンロードサイト」の行政区域データ・地価公示データを読み込みます。
# ファイルパスを指定
DISTRICT_PATH = 'data/N03-20260101_27_GML/N03-20260101_27.shp' # ポリゴンデータ:大阪府(2026年版)
LAND_PATH     = 'data/L01-26_27_GML/L01-26_27.shp'             # 地価公示:大阪府(2026年版)

# データを読込
gdf_district = gpd.read_file(DISTRICT_PATH, encoding='UTF-8') # (2026年版の場合)
gdf_land     = gpd.read_file(LAND_PATH, encoding='shift-jis') # (2026年版の場合)

# 行政区域データを取得
gdf_district         = gdf_district[['N03_004', 'N03_005', 'N03_007', 'geometry']] # (2026年版の場合)
gdf_district.columns = ['city1', 'city2', 'd_code', 'geometry']

# 地価公示データを取得
gdf_land         = gdf_land[['L01_024', 'L01_001', 'L01_008', 'geometry']] # (2026年版の場合)
gdf_land.columns = ['city', 'd_code', 'price', 'geometry']

# データを整形
dst_proj     = 6668
gdf_district = gdf_district.to_crs(epsg=dst_proj) # 空間座標系を再設定
gdf_land     = gdf_land.to_crs(epsg=dst_proj)     # 空間座標系を再設定

# データを加工
gdf_land['log_price'] = np.log(gdf_land['price']) # 対数地価公示価格
事前に保存しておいた行政区域のポリゴンデータと地価公示データを読み込みます。
必要に応じて扱いやすいようにデータを整形しておきます。
行政区域データをまとめます。
# データを統合
gdf_target = gdf_district.dissolve(by='d_code', as_index=False) # 飛び地を統合
gdf_target = gdf_target.merge(
    gdf_land.groupby('d_code')['log_price'].mean(),
    on='d_code'
) # 平均対数地価公示価格
gdf_target['centroids'] = gdf_target['geometry'].centroid # 重心座標

# データフレームを整形
gdf_target = gdf_target.reindex(
    columns=['city1', 'city2', 'd_code', 'log_price', 'geometry', 'centroids']
) # (目視での確認用)
市区町村(行政区域コード)ごとに、飛び地などのポリゴンデータをまとめて、重心座標を求めます。(この処理だと警告文が出ますが、ここでの目的には影響しない誤差なので無視します。)
また、市区町村ごとに対数地価公示価格の平均を計算して、データフレームに結合します。
大阪市のデータを取り出します。
# 地域を指定
city_name = '大阪市'

# データを抽出
gdf_target = gdf_target[gdf_target['city1'] == city_name]
gdf_target.head()
| city1 | city2 | d_code | log_price | geometry | centroids | |
|---|---|---|---|---|---|---|
| 0 | 大阪市 | 都島区 | 27102 | 13.013004 | POLYGON ((135.51481 34.72057, 135.51489 34.720... | POINT (135.52721 34.71193) |
| 1 | 大阪市 | 福島区 | 27103 | 13.507231 | POLYGON ((135.46247 34.6874, 135.46253 34.6879... | POINT (135.47534 34.6939) |
| 2 | 大阪市 | 此花区 | 27104 | 12.339599 | MULTIPOLYGON (((135.34359 34.62112, 135.34357 ... | POINT (135.42011 34.668) |
| 3 | 大阪市 | 西区 | 27106 | 14.140507 | POLYGON ((135.46667 34.67284, 135.4642 34.6747... | POINT (135.48375 34.67776) |
| 4 | 大阪市 | 港区 | 27107 | 12.555794 | MULTIPOLYGON (((135.43006 34.64979, 135.43006 ... | POINT (135.45084 34.66032) |
大阪府全域だとゴチャゴチャして分かりにくいので、大阪市内の区のデータを利用することにします。
以上で、検定に利用する地理空間データを用意できました。
スポンサードリンク
検定の処理
次は、ローカル・モランのIの優位性検定を実行する関数を作成して、データからローカル・モランのIのp値を計算します。
実装
空間ラグの計算を自作関数として定義します。
# SLの計算を実装
def calc_SL(x, W):

    # 偏差を計算
    x_dev = x - np.mean(x)

    # SLを計算
    SL = W @ x_dev
    return SL
空間ラグの計算については「【Python】2.3:空間ラグの実装【空間DS入門のノート】 - からっぽのしょこ」を参照してください。
GMIの計算を自作関数として定義します。
# GMIの計算を実装
def calc_GMI(x, W, ddof=0):

    # 偏差を計算
    x_dev = x - np.mean(x)

    # 分散を計算
    x_var = np.var(x, ddof=ddof)

    # GMIを計算
    GMI  = (x_dev.T @ W @ x_dev).squeeze()
    GMI /= np.sum(W) * x_var
    return GMI
GMIの計算については「【Python】2.3:空間的自己相関(Global Moran's I)の実装【空間データサイエンス入門のノート】 - からっぽのしょこ」を参照してください。
LMIの計算を自作関数として定義します。
# LMIの計算を実装
def calc_LMI(x, W, ddof=0):

    # 偏差を計算
    x_dev = x - np.mean(x)

    # 標本分散を計算
    x_var = np.var(x, ddof=ddof)

    # SLを計算
    SL = W @ x_dev

    # LMIを計算
    LMI  = x_dev / x_var * SL
    return LMI
LMIの計算については「【Python】2.4:ローカル・モランのIの実装【空間DS入門のノート】 - からっぽのしょこ」を参照してください。
LMIの優位性検定におけるp値の計算を自作関数として定義します。
# LMIの優位性検定を実装
def local_moran_test(x, W, iteration=999, alternative='two-sided'):

    # 形状を調整
    x = x.flatten()

    # 地域数を設定
    N = len(x)

    # 標本統計量を計算
    x_dev = x - np.mean(x)    # 偏差
    x_var = np.var(x, ddof=0) # 標本分散

    # LMIを計算:(観測値)
    LMI_obs = calc_LMI(x, W, ddof=0)

    # 乱数生成器を作成
    rng = np.random.default_rng()

    # 受け皿を初期化
    cnts = np.zeros(N, dtype=np.int16)

    # 地域ごとに検定
    for i in range(N):

        # カウントを初期化
        extreme_cnt = 0

        # 置換検定
        for _ in range(iteration):

            # データを置換
            d_perm       = x_dev.copy() # 偏差を複製
            mask         = np.arange(N) != i # 置換対象のインデックス
            d_perm[mask] = rng.permutation(d_perm[mask]) # 偏差を並べ替え

            # LMIを計算:(置換値)
            SL_perm_i  = np.sum(W[i] * d_perm)
            LMI_perm_i = x_dev[i] / x_var * SL_perm_i

            # 置換値と観測値を比較
            if alternative == 'two-sided': # 両側検定:(HH, HL, LH, LL)
                is_extreme = np.abs(LMI_perm_i) >= np.abs(LMI_obs[i])
            elif alternative == 'greater': # 右側検定:(HH, LL)
                is_extreme = LMI_perm_i >= LMI_obs[i]
            elif alternative == 'less':    # 左側検定:(HL, LH)
                is_extreme = LMI_perm_i <= LMI_obs[i]

            # 棄却域に入る値をカウント
            if is_extreme:
                extreme_cnt += 1

        # 結果を記録
        cnts[i] = extreme_cnt

    # p値を計算
    p = (cnts + 1) / (iteration + 1)
    return p
優位性検定やp値の計算については「
【Python】2.3:グローバル・モランのIの優位性検定の実装【空間DS入門のノート】 - からっぽのしょこ」を参照してください。
検定
入力データを設定します。
# データを取得
x = gdf_target['log_price'].to_numpy()
print(x[:5].round(2))
print(x.shape)
[13.01 13.51 12.34 14.14 12.56]
(24,)
個の地域のデータ
を作成します。
この例では、平均対数地価公示価格を使います。
空間重み行列を作成します。
# 空間重み行列を作成
adj_obj = weights.Rook.from_dataframe(
    df=gdf_target, geom_col='geometry', use_index=False
)
adj_obj.transform = 'R' # 正規化
W, _ = adj_obj.full()
print(W[:5, :5].round(2))
print(W.shape)
[[0.   0.   0.   0.   0.  ]
 [0.   0.   0.2  0.2  0.  ]
 [0.   0.25 0.   0.25 0.25]
 [0.   0.14 0.14 0.   0.14]
 [0.   0.   0.33 0.33 0.  ]]
(24, 24)
空間重み行列 を作成します。
この例では、ルーク型の空間隣接行列を用いて、空間重み行列を作成しています。
空間重み行列については「【Python】2.2:空間重み行列の作図:境界の共有【空間データサイエンス入門のノート】 - からっぽのしょこ」を参照してください。
LMIの優位性検定におけるp値を計算します。
# p値を計算
p = local_moran_test(x, W, iteration=999, alternative='two-sided')
print(p[:5].round(3))
print(p.shape)
[0.073 0.344 0.593 0.044 0.976]
(24,)
自作関数を使って、 個の地域のLMIのp値
を計算します。
以上で、作図に利用する検定結果が得られました。
スポンサードリンク
グラフの作成
最後に、LISAクラスターマップを作成します。
モラン散布図やカテゴリ分けについては「【Python】2.3:モラン散布図の作成【空間DS入門のノート】 - からっぽのしょこ」を参照してください。
pysal や splot ライブラリを利用して作図する方法は本を参照してください。
有意水準を設定します。
# 有意水準を指定
alpha = 0.05
有意水準 を指定します。
作図データを格納します。
# 地域数を取得
N = len(gdf_target)

# 値を格納
gdf_target['deviation']   = x - np.mean(x) # 偏差
gdf_target['spatial_lag'] = calc_SL(x, W)  # 空間ラグ
gdf_target['LMI']         = calc_LMI(x, W) # LMI
gdf_target['p_value']     = p              # p値
データフレームに作図に利用する値を格納します。
データの確認
データをコロプレス図で確認します。
作図コード(クリックで展開)
# 配色の範囲を設定
u = 0.5
x_min = gdf_target['log_price'].min()
x_max = gdf_target['log_price'].max()
x_min = np.floor(x_min /u)*u # u単位で切り下げ
x_max = np.ceil(x_max /u)*u  # u単位で切り上げ
u = 0.1
d_size = gdf_target['deviation'].abs().max()
d_size = np.ceil(d_size /u)*u  # u単位で切り上げ
u = 0.1
sl_size = gdf_target['spatial_lag'].abs().max()
sl_size = np.ceil(sl_size /u)*u  # u単位で切り上げ
u = 0.1
lmi_size = gdf_target['LMI'].abs().max()
lmi_size = np.ceil(lmi_size /u)*u  # u単位で切り上げ

# データを作図
fig, axes = plt.subplots(
    nrows=2, ncols=2,
    figsize=(18, 12), dpi=100, facecolor='white',
    constrained_layout=True
)
fig.suptitle('choropleth map', fontsize=20)

## 入力データの作図

# ラベルを作成
fml_lbl = '$x_i$'

## 入力データを描画
ax = axes[0, 0]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='log_price',
    cmap='viridis', vmin=x_min, vmax=x_max,
    legend=True, legend_kwds={'label': fml_lbl, 'shrink': 0.9}
) # 入力データ
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title('input data', fontsize=20)
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

## 偏差の作図

# ラベルを作成
fml_lbl = '$x_i - \\bar{x}$'

# 偏差を描画
ax = axes[1, 0]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='deviation',
    cmap='coolwarm', vmin=-d_size, vmax=d_size,
    legend=True, legend_kwds={'label': fml_lbl, 'shrink': 0.9}
) # 偏差
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title('deviation', fontsize=20)
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

## SLの作図

# ラベルを作成
fml_lbl = '$SL_i = \\sum_{i=1}^N w_{ij} (x_j - \\bar{x})$'

# SLを描画
ax = axes[0, 1]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='spatial_lag',
    cmap='coolwarm', vmin=-sl_size, vmax=sl_size,
    legend=True, legend_kwds={'label': fml_lbl, 'shrink': 0.9}
) # 空間ラグ
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title('spatial lag', fontsize=20)
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

## LMIの作図

# ラベルを作成
fml_lbl = '$LMI_i = \\frac{x_i - \\bar{x}}{s^2} SL_i$'

# LMIを描画
ax = axes[1, 1]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='LMI',
    cmap='coolwarm', vmin=-lmi_size, vmax=lmi_size,
    legend=True, legend_kwds={'label': fml_lbl, 'shrink': 0.9}
) # LMI
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title("local Moran's I", fontsize=20)
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

plt.show()
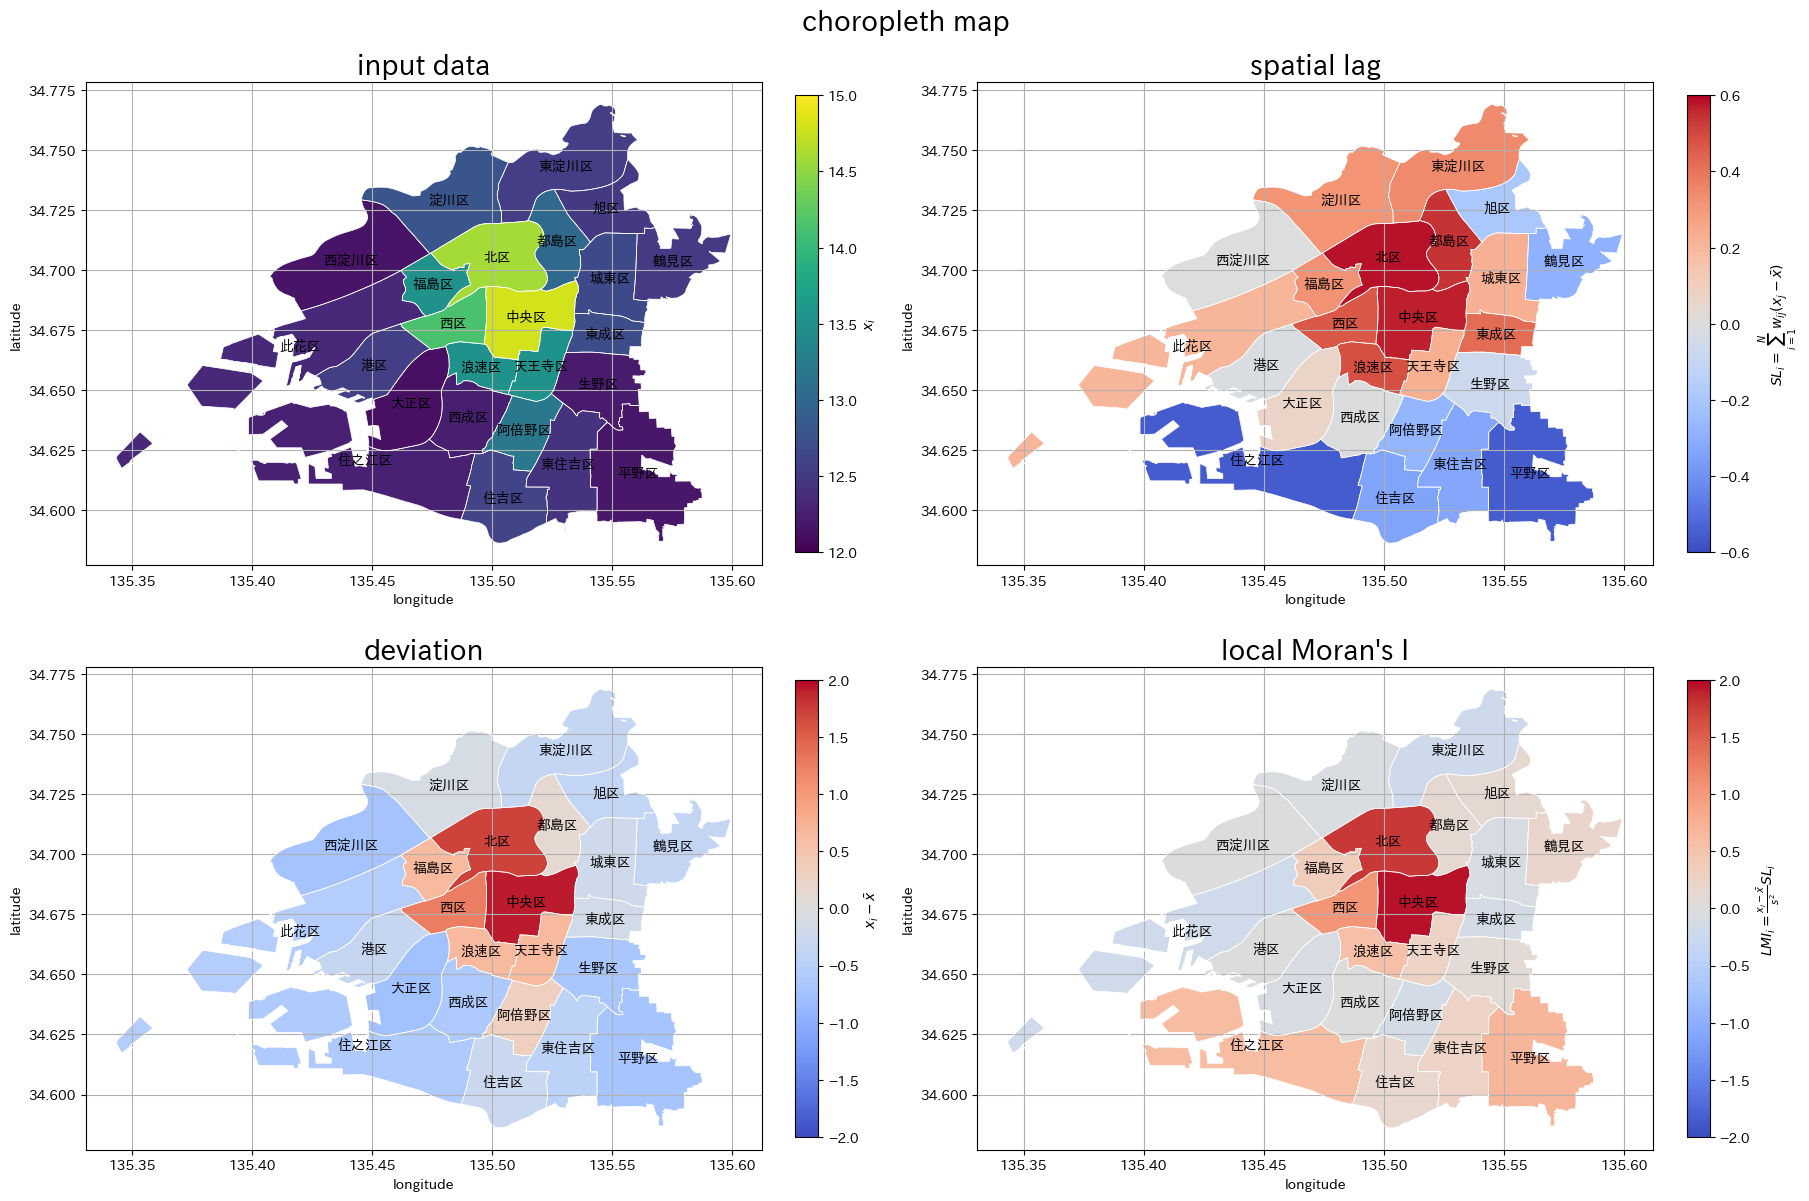
左上図はデータの値(平均対数地価公示価格)、左下図は偏差の値、右上図は空間ラグの値、右下図はLMIの値をグラデーションで示します。偏差・空間ラグ・LMIの図に関しては、0を中心とする範囲でグラデーション(値が0のとき灰色、値が小さいほど濃い青色、値が大きいほど濃い赤色)を設定しています。
結果の確認
モラン散布図のカテゴリをグラフで確認します。
作図コード(クリックで展開)
# カテゴリを割当
gdf_target['quadrant'] = np.select(
    [
        (gdf_target['deviation'] >= 0.0) & (gdf_target['spatial_lag'] >= 0.0), # High-High
        (gdf_target['deviation'] < 0.0)  & (gdf_target['spatial_lag'] >= 0.0), # Low-High
        (gdf_target['deviation'] < 0.0)  & (gdf_target['spatial_lag'] < 0.0),  # Low-Low
        (gdf_target['deviation'] >= 0.0) & (gdf_target['spatial_lag'] < 0.0)   # High-Low
    ],
    [1, 2, 3, 4],
    default=0
) # 象限番号
# カラーマップを作成
cmap = ListedColormap([
    'hotpink',   # High-High
    'orange',    # Low-High
    'royalblue', # Low-Low
    'limegreen'  # High-Low
])
# GMIを計算
GMI = calc_GMI(x, W)

# 軸の範囲を設定
u = 0.5
axis_x_size = gdf_target['deviation'].abs().max()
axis_y_size = gdf_target['spatial_lag'].abs().max()
axis_x_size = np.ceil(axis_x_size /u)*u # u単位で切り上げ
axis_y_size = np.ceil(axis_y_size /u)*u # u単位で切り上げ

# ラベルを作成
param_lbl = f'$N = {N}, GMI = {GMI:.2f}$'

# モラン散布図を作成
fig, axes = plt.subplots(
    nrows=2, ncols=1,
    figsize=(9, 12), dpi=100, facecolor='white',
    constrained_layout=True
)
fig.suptitle('Moran scatterplot', fontsize=20)

## モラン散布図の作成

# モラン散布図を描画
ax = axes[0]
ax.plot(
    [[-axis_x_size, 0.0], [axis_x_size, 0.0]],
    [[0.0, -axis_y_size], [0.0, axis_y_size]],
    color='black', linewidth=1.0, linestyle='--',
    zorder=10
) # xy軸線
ax.axline(
    xy1=(0, 0), slope=GMI,
    color='red', linewidth=1.0, linestyle='-',
    label='Moran regression line',
    zorder=11
) # 回帰直線
scatter = ax.scatter(
    x=gdf_target['deviation'],
    y=gdf_target['spatial_lag'],
    cmap=cmap, c=gdf_target['quadrant'],
    s=50,
    zorder=20
) # 偏差 - 空間ラグ
for i in range(N):
    # ラベルの表示位置を調整
    area_x, area_y, area_lbl = gdf_target.loc[i, ['deviation', 'spatial_lag', 'city2']]
    offset_x = 0.0 # 調整幅を指定
    offset_y = 0.05 # 調整幅を指定
    offset_x *= np.sign(area_x)
    offset_y *= np.sign(area_y)
    offset_x = offset_x if area_x+offset_x <= axis_x_size else axis_x_size-area_x
    offset_x = offset_x if area_x+offset_x >= -axis_x_size else -axis_x_size-area_x
    offset_y = offset_y if area_y+offset_y <= axis_y_size else axis_y_size-area_y
    offset_y = offset_y if area_y+offset_y >= -axis_y_size else -axis_y_size-area_y
    ax.annotate(
        text=area_lbl, xy=(area_x, area_y),
        xytext=(area_x+offset_x, area_y+offset_y),
        ha='center', va='center', rotation=0,
        arrowprops=dict(
            arrowstyle='-', color='black', linewidth=0.5
        ),
        size=10,
        zorder=21
    ) # 地域名
ax.set_xlabel('deviation')
ax.set_ylabel('spatial lag')
ax.set_title(param_lbl, loc='left')
ax.grid()
ax.set_xlim(xmin=-axis_x_size, xmax=axis_x_size)
ax.set_ylim(ymin=-axis_y_size, ymax=axis_y_size)

# 凡例を設定
handles, _ = scatter.legend_elements()
labels     = ['High-High', 'Low-High', 'Low-Low', 'High-Low']
ax.legend(
    handles=handles, labels=labels,
    title='quadrant', loc='upper left'
)

## カテゴリの作図

# モラン散布図のカテゴリを描画
ax = axes[1]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='quadrant',
    cmap=cmap, categorical=True
) # 象限番号
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

plt.show()
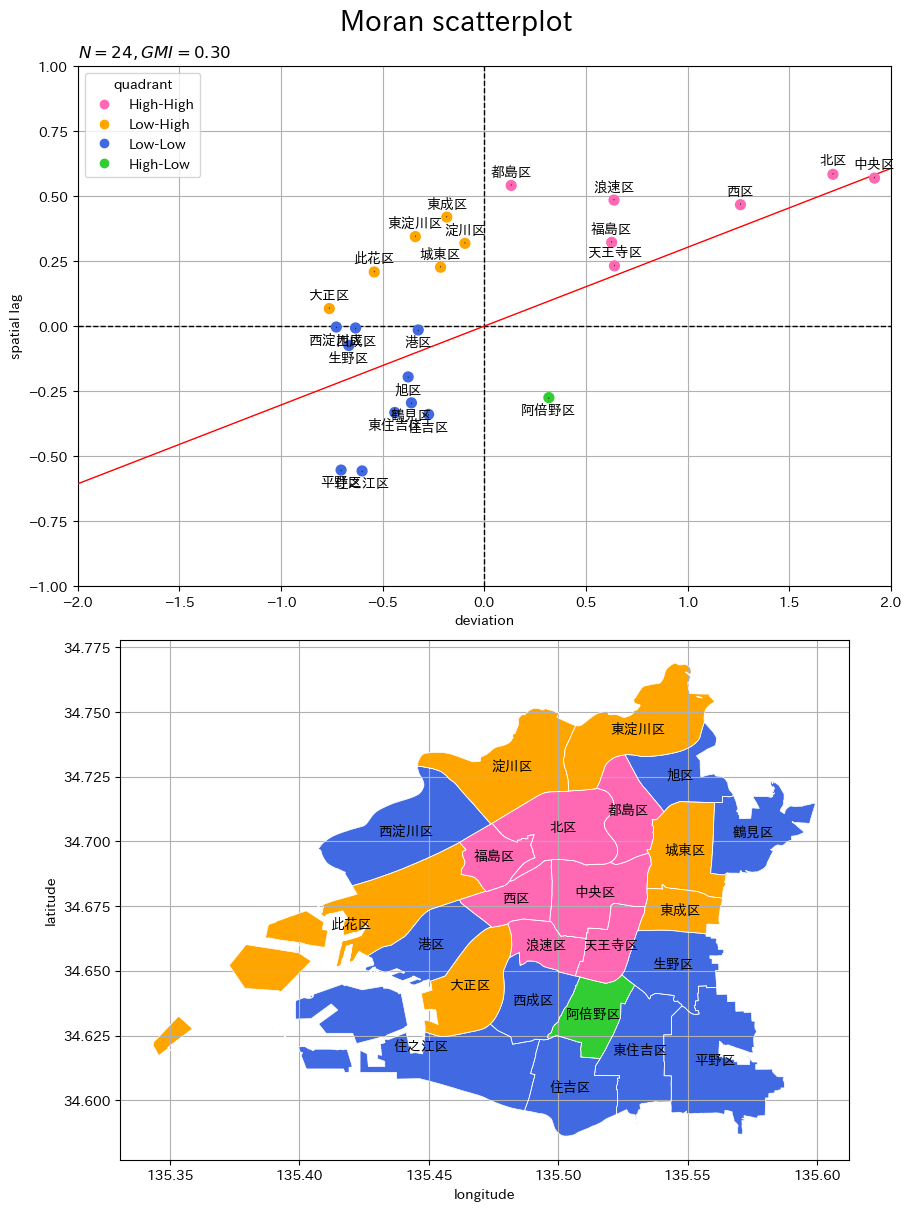
上図は、モラン散布図であり、横軸は偏差、縦軸は空間ラグです。
下図は、モラン散布図における各地域のカテゴリ(各地域が属する象限番号)を地図上の塗りつぶしの色で示します。
優位性検定の結果をグラフで確認します。
作図コード(クリックで展開)
# 値を格納
gdf_target['signif_flg'] = (p < alpha).astype(np.int8) # 有意性フラグ
gdf_target['signif_lbl'] = gdf_target['signif_flg'].map(
    {0: 'not significant', 1: 'significant'}
) # 優位性ラベル
# 配色の範囲を設定
p_min, p_max = 0.0, 1.0 # 最小値, 最大値

# 検定結果を作図
fig, axes = plt.subplots(
    nrows=2, ncols=1,
    figsize=(9, 12), dpi=100, facecolor='white',
    constrained_layout=True
)
fig.suptitle('choropleth map', fontsize=20)

## p値の作図

# ラベルを作成
param_lbl = f'$N = {N}$'

# p値を描画
ax = axes[0]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='white', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='p_value',
    cmap='Reds_r', vmin=p_min, vmax=p_max,
    legend=True, legend_kwds={'label': 'p value', 'shrink': 1.0}
) # p値
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title(param_lbl, loc='left')
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

## 優位性の作図

# ラベルを作成
param_lbl = f'$\\alpha = {alpha}$'

# 有意性を描画
ax = axes[1]
gdf_target.boundary.plot(
    ax=ax,
    edgecolor='black', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='signif_lbl',
    cmap='Paired', categorical=True,
    legend=True, legend_kwds={'loc': 'upper left'}
) # 有意性
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title(param_lbl, loc='left')
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

plt.show()
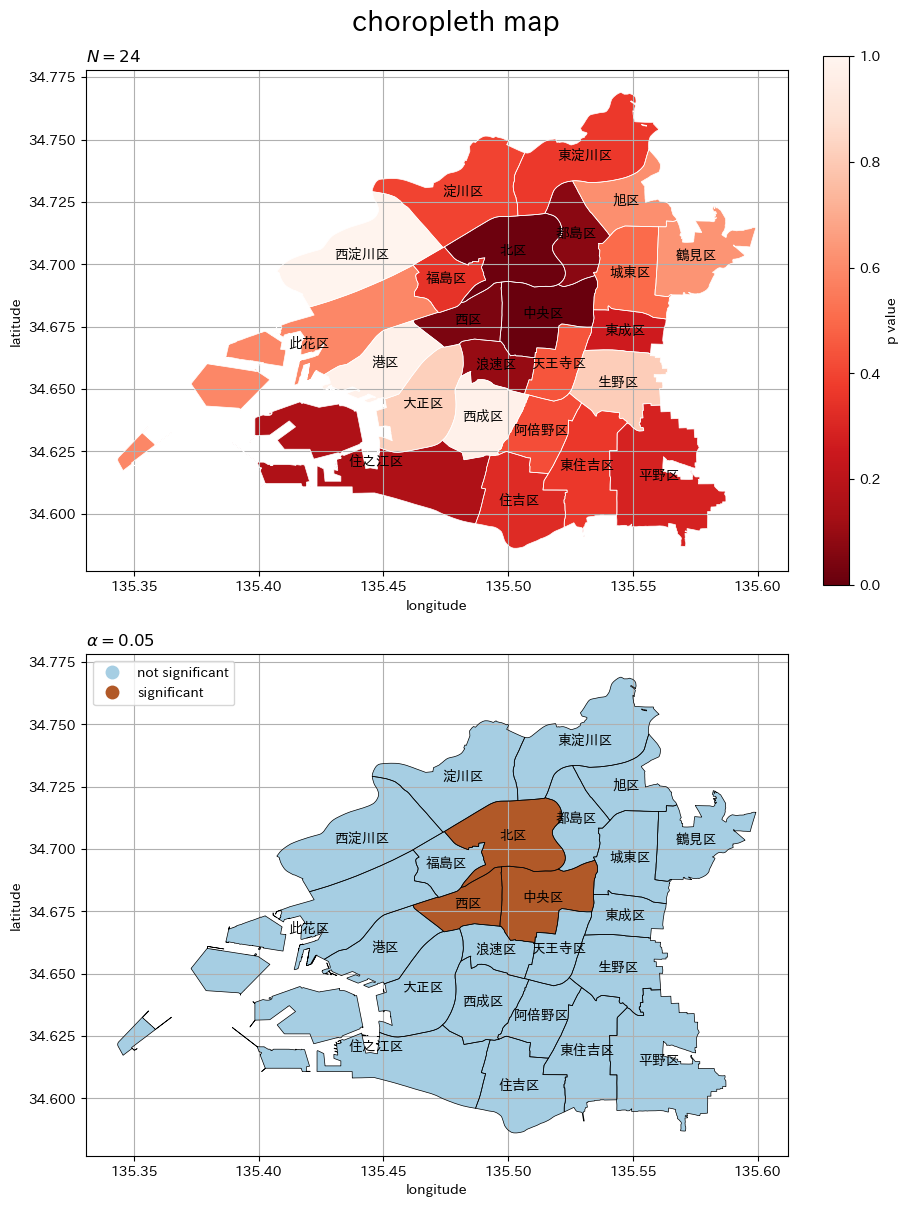
上図はp値をグラデーション、下図は優位性を塗りつぶし色で示します。
LMIが有意な地域( である地域
)と、非有意な地域(
である地域
)を確認できます。
LISAクラスターマップ
平均値に対する大小関係(各地域の符号)のカテゴリを、優位性を反映して割り当てます。
# カテゴリを割当
gdf_target['dev_type'] = np.where(
    gdf_target['deviation'] >= 0.0, 'High', 'Low'
) # 横軸の High,Low
gdf_target['sl_type'] = np.where(
    gdf_target['spatial_lag'] >= 0.0, 'High', 'Low'
) # 縦軸の High,Low
gdf_target['moran_type'] = gdf_target['dev_type'] + '-' + gdf_target['sl_type'] # カテゴリラベル
gdf_target['quadrant'] = np.select(
    [
        (gdf_target['deviation'] >= 0.0) & (gdf_target['spatial_lag'] >= 0.0), # High-High
        (gdf_target['deviation'] < 0.0)  & (gdf_target['spatial_lag'] >= 0.0), # Low-High
        (gdf_target['deviation'] < 0.0)  & (gdf_target['spatial_lag'] < 0.0),  # Low-Low
        (gdf_target['deviation'] >= 0.0) & (gdf_target['spatial_lag'] < 0.0)   # High-Low
    ],
    [1, 2, 3, 4],
    default=0
) # 象限番号

# 有意性を反映
mask = p > alpha # 非有意のインデックス
gdf_target['lisa_cluster']            = gdf_target['moran_type'].copy() # カテゴリを複製
gdf_target.loc[mask, 'lisa_cluster']  = 'not significant' # 非有意を置換
gdf_target['lisa_quadrant']           = gdf_target['quadrant'].copy() # カテゴリを複製
gdf_target.loc[mask, 'lisa_quadrant'] = 0 # 非有意を置換

# データを確認
gdf_target[
    ['city2', 'deviation', 'spatial_lag', 'dev_type', 'sl_type', 'moran_type', 'quadrant', 'lisa_cluster', 'lisa_quadrant']
].head()
| city2 | deviation | spatial_lag | dev_type | sl_type | moran_type | quadrant | lisa_cluster | lisa_quadrant | |
|---|---|---|---|---|---|---|---|---|---|
| 0 | 都島区 | 0.131964 | 0.540768 | High | High | High-High | 1 | not significant | 0 |
| 1 | 福島区 | 0.626191 | 0.321787 | High | High | High-High | 1 | not significant | 0 |
| 2 | 此花区 | -0.541442 | 0.208086 | Low | High | Low-High | 2 | not significant | 0 |
| 3 | 西区 | 1.259467 | 0.466808 | High | High | High-High | 1 | High-High | 1 |
| 4 | 港区 | -0.325246 | -0.014860 | Low | Low | Low-Low | 3 | not significant | 0 |
偏差(横軸)と空間ラグ(縦軸)の符号(0より大きいか小さいか)によりそれぞれ 'High', 'Low' のラベルを割り当て、2つのラベルを文字列結合して象限ごと(4パターン)のラベル(カテゴリ)と象限番号(カテゴリ番号)を作成します。
p値 が有意水準
より大きい(非有意
)地域のカテゴリラベルとカテゴリ番号を置き換えます。
LISAクラスターマップ(優位性を反映したモラン散布図のカテゴリカルマップ)を作成します。
# カラーマップを作成
cmap = ListedColormap([
    'hotpink',   # High-High
    'orange',    # Low-High
    'royalblue', # Low-Low
    'limegreen', # High-Low
    'lightgray'  # 非有意
])

# カテゴリ順(カテゴリ名と色名の対応)を指定
categories = [
    'High-High',
    'Low-High',
    'Low-Low',
    'High-Low',
    'not significant'
]

# カテゴリ順を設定
dtype = CategoricalDtype(
    categories=categories,  ordered=True
)
gdf_target['lisa_cluster'] = gdf_target['lisa_cluster'].astype(dtype)
# ラベルを作成
param_lbl = f'$N = {N}, \\alpha = {alpha}$'

# LISAクラスターマップを作成
fig, ax = plt.subplots(
    figsize=(8, 6), dpi=100, facecolor='white',
    constrained_layout=True
)
fig.suptitle('LISA cluster map', fontsize=20)

gdf_target.boundary.plot(
    ax=ax,
    edgecolor='black', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax, column='lisa_cluster',
    cmap=cmap, categorical=True,
    legend=True, legend_kwds={
        'title': 'quadrant', 'loc': 'upper left'
    }
) # モラン散布図のカテゴリ
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title(param_lbl, loc='left')
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

plt.show()
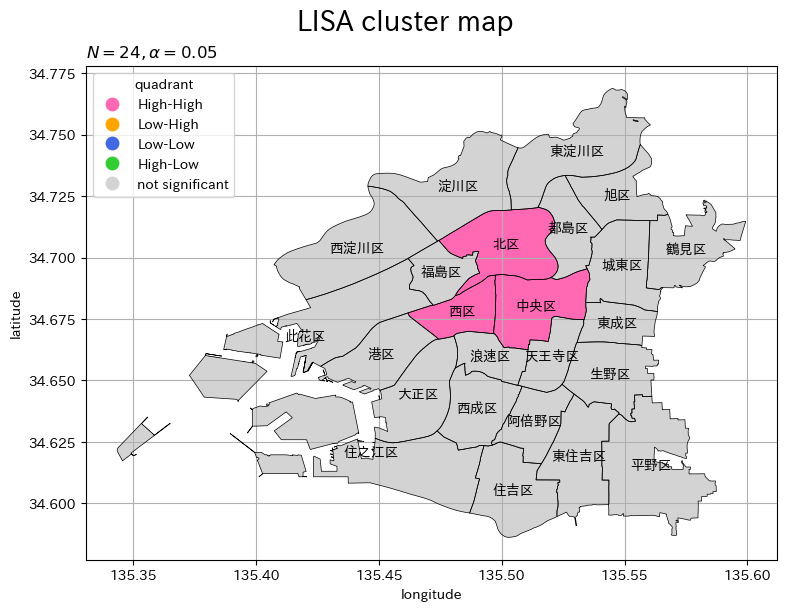
LMIが有意な地域のカテゴリ(モラン散布図における象限番号)を塗りつぶしの色で示します。非有意な地域は灰色で塗りつぶします。
GeoDataFrameと gdf.plot() を使って、カテゴリカル・コロプレス図を描画します。categorical 引数に True を指定すると離散型のデータ(カテゴリデータ)として扱われます。データ列の引数 column にカテゴリラベル(やカテゴリ番号)の列、カラーマップの引数 cmap に離散型のカラーマップを指定します。
この例では、凡例に(カテゴリ番号ではなく)カテゴリラベルを表示するために、カテゴリ番号に対応するようにカテゴリラベルにPandasのCategorical型の順序を指定しています。Categorical型の順序は、CategoricalDtype() で設定できます。
または、辞書型のオブジェクトを使って配色を設定します。
# カラーマップを作成
colors = {
    'High-High': 'hotpink',   # High-High
    'Low-High':  'orange',    # Low-High
    'Low-Low':   'royalblue', # Low-Low
    'High-Low':  'limegreen', # High-Low
    'not significant': 'lightgray' # 非有意
}
# ラベルを作成
param_lbl = f'$N = {N}, \\alpha = {alpha}$'

# LISAクラスターマップを作成
fig, ax = plt.subplots(
    figsize=(8, 6), dpi=100, facecolor='white',
    constrained_layout=True
)
fig.suptitle('LISA cluster map', fontsize=20)

gdf_target.boundary.plot(
    ax=ax,
    edgecolor='black', linewidth=0.5
) # 行政区界
gdf_target.plot(
    ax=ax,
    color=gdf_target['lisa_cluster'].map(colors), categorical=True
) # モラン散布図のカテゴリ
for n in range(N):
    area_x, area_y = gdf_target.loc[n, 'centroids'].coords[0] # 座標
    area_lbl       = gdf_target.loc[n, 'city2'] # 地域名
    ax.text(
        x=area_x, y=area_y, s=area_lbl, ha='center', va='center',
        size=10
    ) # 地域名
ax.set_xlabel('longitude')
ax.set_ylabel('latitude')
ax.set_title(param_lbl, loc='left')
ax.grid()
ax.set_aspect(aspect='equal', adjustable='box')

# 凡例を設定
handles = [
    mpatches.Patch(color=color, label=label) for label, color in colors.items()
]
ax.legend(
    handles=handles,
    title='LISA cluster', loc='upper left'
)

plt.show()
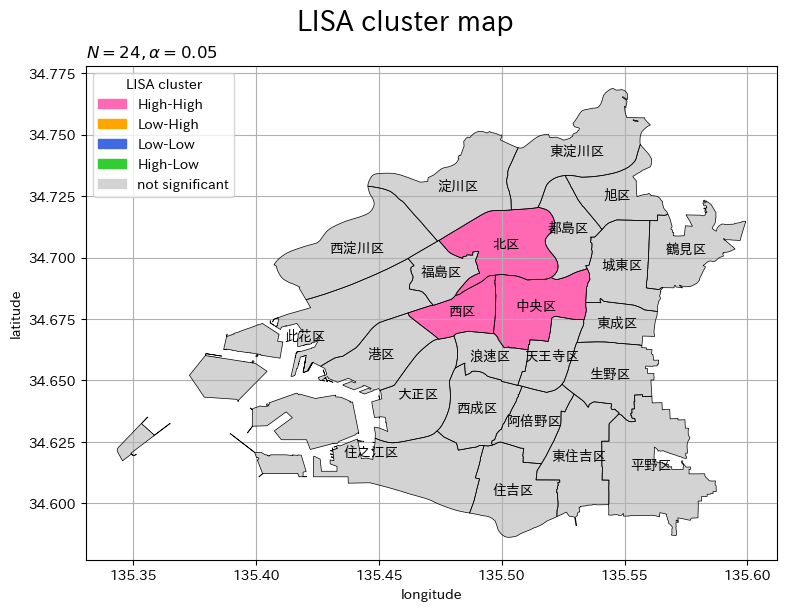
この例では、辞書型のオブジェクトとしてカラーマップを作成しています。カテゴリ名をキー、色名を値として配色を指定します。
カテゴリラベル列の文字列をキーとして、辞書型のカラーマップから .map() で対応する色名を取り出して、塗りつぶし色の引数 color に色を指定します。
LMIが有意な地域( である地域
)に関して、ホットスポット(High-High・桃色)、ドーナツ(Low-High・オレンジ色)、コールドスポット(Low-low・青色)は、ダイヤモンドインザラフ(High-Low・緑色)の4つのカテゴリと、非有意な地域(
である地域
)のカテゴリなしを確認できます。
以上で、LISAクラスターマップを作成できました。
この記事では、LISAクラスターマップを確認しました。
参考文献

おわりに
専用のライブラリを使えば関数一発で作成できる図と聞くと、素のMatplotlibで図を再現したくなってしまうんです。
ここまで補足記事のつもりで書いた寄り道気味の記事が続きましたが、なんだかここまでの内容を全て詰め込んだ図ができて、大団円を迎えられたって感じの記事になりました。
最後に、えびちゅうのライブ映像をどうぞ♪
今年のFAMIENのDAY1の日ということで🗻私は毎年自宅からですが⛲TVでも楽しい🔥
【次の内容】
線形回帰モデルの仮定を数式で確認します。
